Formal program evaluation ratings were supposed to make the federal budget legible: score every program, publish the score, and fund the winners. The best-known attempt, the Bush administration's Program Assessment Rating Tool, scored roughly a thousand programs and published the results. It did not last, and the reason it did not last says more about budgeting than any scorecard ever did.
PART ran from fiscal year 2004 through 2008. It assigned each assessed program one of five ratings — effective, moderately effective, adequate, results not demonstrated, or ineffective — based on a standard questionnaire covering design, planning, management, and results. The mechanism was clear: a low score was meant to pressure both the agency and the appropriators. What the record shows is that the score moved documents more reliably than it moved dollars, and that the tool's successors have quietly narrowed its ambitions rather than revived them.
How PART actually worked
The Program Assessment Rating Tool was built and run by the Office of Management and Budget, not by Congress. According to the OMB PART documentation archive, a PART review examined four things: program purpose and design, performance measurement and strategic planning, program management, and program results. Because every program answered the same series of analytical questions, OMB argued, scores could be compared across similar programs and tracked over time. The results were published on ExpectMore.gov, which carried nearly 1,000 completed assessments.
Each assessment produced a numerical score converted to an adjectival rating. The lowest common outcome, "results not demonstrated," was often a measurement verdict rather than a performance verdict: the program lacked the data to prove it worked. That distinction mattered, because a program could be well run and still score poorly for the sin of not having built an evidence system. The rating described the paperwork as much as the program.
Did the ratings change budgets?
This is the durable question, and the honest answer is: sometimes, and rarely as designed. A low rating gave an administration a documented argument for trimming or restructuring a program. But appropriation decisions sat with Congress, and Congress had its own constituencies. Programs with poor scores continued to be funded when legislators valued them; the rating functioned as negotiating leverage, not as an automatic trigger. No published rule ever made a PART score binding on an appropriation.
The deeper problem was structural. OMB both produced the ratings and used them in the President's budget, so agencies experienced the process as advocacy by the budget office rather than neutral audit. Appeals processes — the guidance archive includes formal appeal forms for measures and non-measures — existed precisely because agencies contested scores. When the assessor is also the budget cutter, the incentive is to dispute the measure, not to fix the program. That dynamic, in which a metric becomes something managed rather than something learned from, is the same pattern documented in When a Measure Becomes a Target: Government Metrics and Gaming. For related coverage, see When a Measure Becomes a Target: Government Metrics and Gaming.
What the ratings did change was behavior inside agencies, mostly in the direction the tool intended but not the one critics feared. Agencies built performance measures, commissioned evaluations, and hired staff to answer PART questions, because the questionnaire rewarded those things. Whether that produced better outcomes is harder to establish than whether it produced better documentation. The evidence systems PART pushed for outlived PART itself.
What replaced the single score
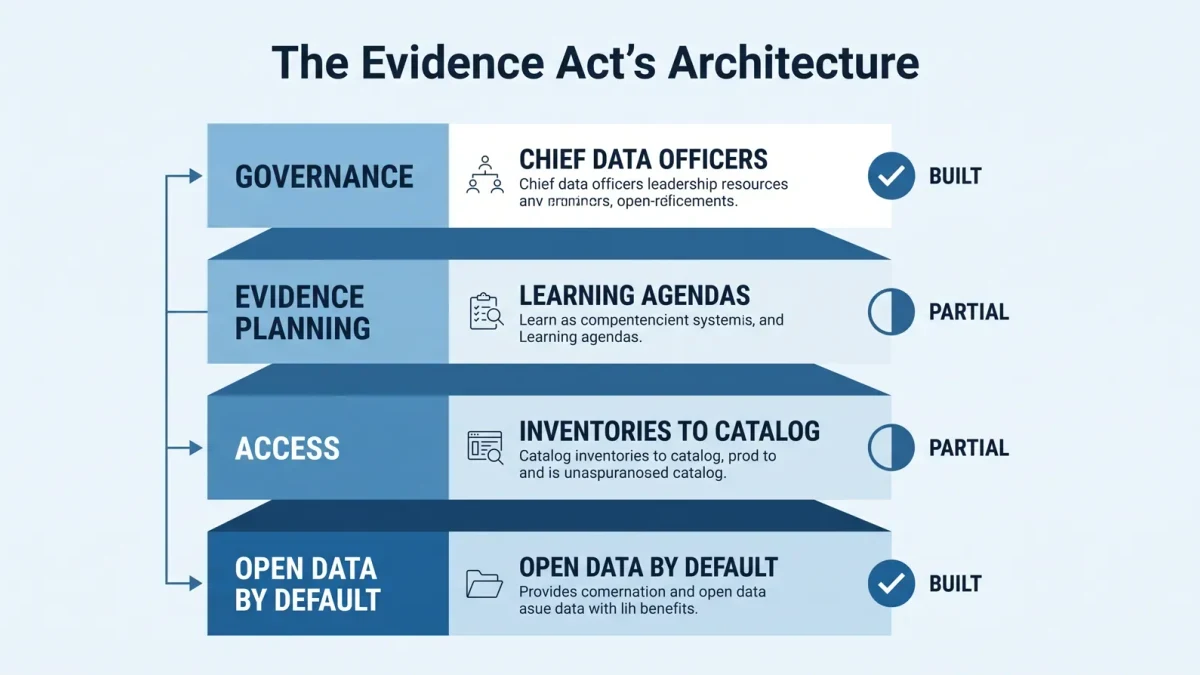
The Obama administration retired PART and shifted to agency-built strategic reviews and performance frameworks, with less emphasis on a public grade for each program. The statutory foundation came later: the Evidence Act required agencies to build evaluation capacity, evidence inventories, and learning agendas — infrastructure rather than scores. As our earlier analysis of that law found, The Evidence Act, Seven Years On: Slow Progress, Real Infrastructure, the emphasis moved from rating programs to building the data systems a rating would depend on. That is a defensible sequencing: PART's most common failure mode was judging programs that could not yet be measured. This connects to our earlier piece, The Evidence Act, Seven Years On: Slow Progress, Real Infrastructure.
The rating impulse did not disappear. It migrated to adjacent systems with narrower scopes. In acquisition, contractor performance has long been scored through CPARS, the Contractor Performance Assessment Reporting System, which used adjectival ratings from Exceptional to Unsatisfactory. According to USFCR, a consulting firm that advises federal contractors, the FY2026 National Defense Authorization Act directs the Department of Defense to move CPARS away from narrative evaluations toward a record of verifiable negative performance events, reported within 30 days of verification, with a composite score weighted by contract volume. The firm also notes that revisions effective April 1, 2026 direct agencies to use past performance information across the acquisition lifecycle, not only at source selection. These are vendor characterizations of the changes, but the direction is notable: fewer adjectives, more documented events.
Personnel ratings are moving the same way. A proposed rule published by the Office of Personnel Management in February 2026 would, according to the Federal Register notice, remove a rating level, require biennial certification of agency appraisal systems, authorize standardized rating distributions, and eliminate the option to grieve a performance rating. OPM's stated concern is that under the current system most employees receive the highest two ratings, which the agency argues blunts the tool's usefulness. The proposal is unfinished — comments were due in March 2026 — so what is known is the direction, not the outcome.
Why the single score keeps failing
Three mechanisms recur across every version of the program evaluation ratings idea. First, the assessor and the funder are rarely separable, so the rating reads as a budget argument rather than a finding. Second, ratings measure what is measurable, which rewards measurement infrastructure and punishes programs serving hard-to-count populations. Third, a public grade invites management of the grade. None of these is a flaw in drafting that a better rubric fixes; they are properties of scoring a political institution.
The local level shows what a quieter version looks like. Writing for the University of North Carolina School of Government, faculty member Obed Pasha describes performance management in community development as an ongoing, cyclical process distinct from one-time program evaluations, and notes that small departments with one or two staff often lack the resources to collect and analyze their own data. That constraint is the honest baseline for most government: the binding limit is rarely the willingness to be scored. It is the capacity to produce the evidence a fair score requires.
What this means for the next rating proposal
Our analysis of the record suggests a practical test for any new program evaluation ratings scheme, including efficiency-rating proposals now circulating in budget debates. Ask three questions. Who assigns the score, and are they institutionally separate from the funding decision? What happens to a program that lacks the data to be scored — is that treated as a finding about the evidence system or a verdict on the program? And is the score published with the underlying questions, so that an outsider can see what a rating actually measured?
PART answered none of these well enough to survive, yet it left a real legacy: ExpectMore.gov's thousand assessments, the habit of standard questionnaires, and the evidence infrastructure the Evidence Act later formalized. The lesson is not that ratings are useless. It is that a rating changes budgets only when it changes the argument available to appropriators — and appropriators respond to constituencies at least as much as to scores. Any successor that pretends otherwise will fail the same way, more quietly.